
Seed Audio - AI Text to Speech and Dialogue Generation Tool

What is Seed Audio
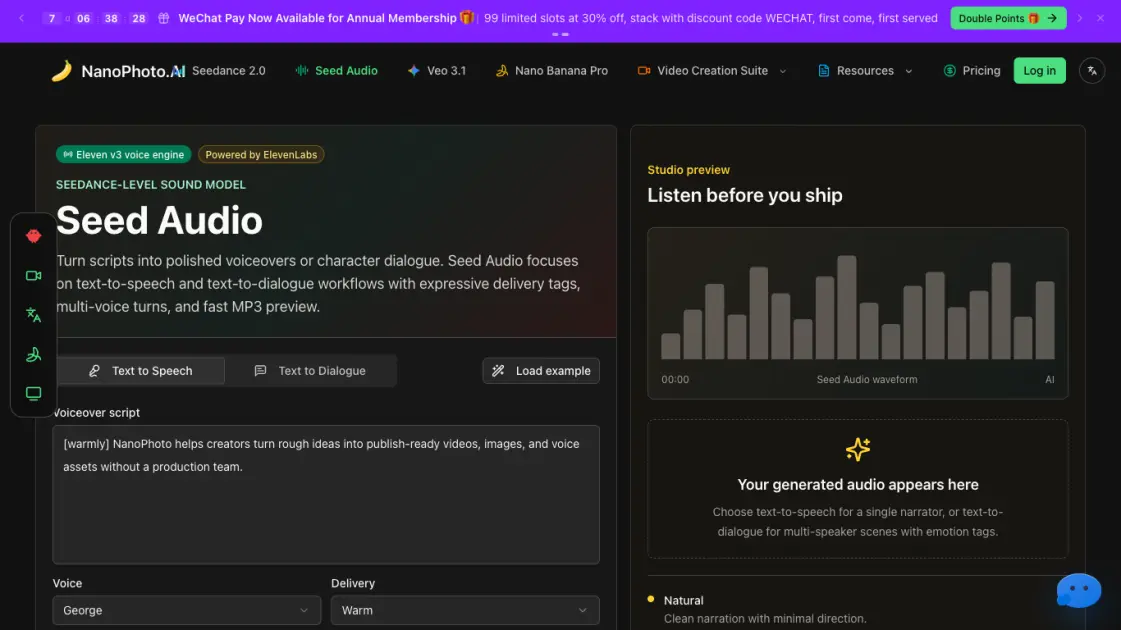
Seed Audio is a text-to-speech and dialogue generation tool built on ElevenLabs infrastructure, accessible through the NanoPhoto platform. The service converts written scripts into MP3 audio with two primary modes: single-voice narration and multi-speaker dialogue with assigned voice turns.
Performance tags such as [laughing], [whispering], [sighs], and [short pause] provide granular control over delivery style. Three preset directions—Natural, Warm, and Cinematic—adjust pacing and tone for different content types including explainers, trailers, and onboarding material.
The workflow follows a write-direct-render-listen-download loop with in-browser MP3 preview before export. Output serves video editing, podcast drafts, ad mockups, and product demos.
How does Seed Audio work
Seed Audio operates through a streamlined four-step workflow powered by ElevenLabs text-to-speech and text-to-dialogue models. Users begin by writing a source script — either a single voiceover paragraph or two to four dialogue turns for multi-speaker scenes. Next, they select voices: a single narrator for text-to-speech mode, or assign distinct voices to each dialogue turn for character-driven conversations. Performance tags such as [warmly], [curious], [laughing], [whispering], [sighs], and [short pause] direct emotional delivery and pacing. Finally, the system renders an MP3 preview playable in-browser, allowing immediate audition before download for video edits, podcast drafts, ad mockups, or product demos.
Benefits of Seed Audio
Seed Audio consolidates text-to-speech and multi-speaker dialogue generation into a single browser tool backed by ElevenLabs, removing the need to switch between separate editors. Performance tags such as [laughing], [whispering], [sighs], and [short pause] provide granular emotional steering across Natural, Warm, and Cinematic delivery styles, while per-turn voice assignment enables believable character exchanges for podcasts, game prototypes, and storyboard demos. The tight write-direct-render-listen-download loop produces publishable MP3s in seconds, though the workflow remains limited to ElevenLabs' voice library with no custom voice training, API access, or batch processing, and the $668 annual price point sits above casual experimentation.
Pros and Cons of Seed Audio
Pros
- Combines TTS and dialogue generation in one tool
- Performance tags steer emotion and delivery
- Multi-voice dialogue scenes with turn assignment
- Fast MP3 preview and download in browser
- Three delivery styles: Natural, Warm, Cinematic
Cons
- Requires ElevenLabs account for generation
- Credit-based pricing model limits usage
- Audio-only output with no video sync
- No custom voice cloning mentioned
- Web-based only, no offline capability
Core Features of Seed Audio
Text-to-Speech Generation
Produces single-narrator voiceovers from scripts, hooks, explainers, and short ad reads with clean, natural delivery.
Text-to-Dialogue Generation
Creates multi-speaker conversations by assigning distinct voices to each turn for demos, podcasts, games, and storyboards.
Performance Tags
Steers vocal delivery using inline tags such as [laughing], [whispering], [sighs], and [short pause] for expressive control.
Delivery Style Presets
Offers three preset styles — Natural for clean narration, Warm for friendly explainers, Cinematic for dramatic pacing.
Per-Turn Voice Selection
Allows individual voice assignment per dialogue turn, enabling believable character exchanges in multi-speaker scenes.
MP3 Preview and Download
Renders audio to MP3 with in-browser playback, then provides downloadable files for video edits, podcast drafts, and demos.
Use Cases of Seed Audio
- Content creators: Generate voiceovers for video edits, trailers, and storyboards with expressive delivery tags
- Podcasters: Produce podcast drafts and multi-speaker dialogue episodes using multi-voice dialogue generation
- Advertisers: Create ad mockups and product demo voiceovers with warm, cinematic, or natural delivery styles
- Game developers: Generate character dialogue and narrative voiceovers for game prototypes and storyboards
- Video editors: Produce quick voiceover drafts for rough cuts, client reviews, and final video exports
FAQs of Seed Audio
What is Seed Audio?
Seed Audio is an AI-powered text-to-speech and text-to-dialogue tool built on ElevenLabs technology and integrated into the NanoPhoto platform. It converts written scripts into spoken audio with expressive performance tags, multi-voice dialogue support, and fast MP3 preview. Users write or paste a script, select a voice, optionally add delivery directions, and generate listenable audio in seconds without leaving the browser.
What is the difference between text-to-speech and text-to-dialogue?
Text-to-speech (TTS) generates a single narrator voiceover from a block of text, ideal for explainers, ad reads, and voiceover drafts. Text-to-dialogue assigns different voices to individual turns in a script, supporting multi-speaker conversations for podcasts, game dialogue, demos, and storyboards. Dialogue mode also accepts per-turn performance tags so each character's delivery can be directed independently.
What performance tags are supported?
Seed Audio recognizes tags such as [laughing], [whispering], [sighs], [short pause], [warmly], [curious], and others that steer the emotional tone and pacing of the output. These tags are inserted directly into the script text at the point where the delivery should change. They work in both TTS and dialogue modes, giving users fine-grained control over how a line sounds without needing external audio editing.
How does Seed Audio pricing work?
Seed Audio uses a credit-based pricing model where each audio generation costs 1 credit. Credits are purchased through the NanoPhoto platform and apply across the product suite. This pay-per-generation model suits users with variable workloads, from occasional voiceover drafts to high-volume dialogue production, without requiring a monthly subscription commitment.
Who is Seed Audio designed for?
Seed Audio targets content creators, video editors, podcasters, game developers, and product teams who need quick, publishable voice assets. It fits workflows where speed matters, such as ad mockups, tutorial voiceovers, character dialogue for indie games, and podcast draft recordings. Users who would otherwise open a dedicated audio studio for every short script can complete the same task in a fraction of the time.
What audio formats does Seed Audio output?
Seed Audio generates MP3 files that can be previewed directly in the browser and downloaded for use in video editing software, podcast production tools, game engines, and presentation decks. MP3 was chosen as the output format for its balance of file size and audio quality, making it practical for quick drafts and final assets alike.
How does Seed Audio compare to standalone TTS tools?
Unlike standalone TTS tools that require switching between applications for script editing, voice selection, and audio export, Seed Audio keeps the entire workflow inside the NanoPhoto platform. Users write, direct, render, listen, and download in one interface. The built-in performance tag system and multi-speaker dialogue mode remove the need for separate audio editing passes for basic delivery adjustments, which reduces iteration time from minutes to seconds per generation.
How to use Seed Audio
Write the source script by entering a voiceover paragraph or two to four dialogue turns, or four dialogue turns focused on natural-sounding speech.
Choose voices and delivery by selecting a narrator voice for text-to-speech or assigning a different voice to each dialogue turn for character exchange.
Add performance tags such as [warmly], [curious], [laughing], or [short pause] to guide emotional delivery and make output feel directed.
Preview the generated MP3 in the browser to verify quality, then download the audio file for video edits, podcast drafts, ad mockups, or product demos.
Seed Audio Website Traffic Analysis
Latest traffic information
- Monthly Visits127.48K
- Bounce Rate40.7%
- Pages Per Visit1.76
- Visit Duration00:00:37
- Global Rank340.66K
- Country/Region Ranking33.75K
Top Keywords
| Keyword | Traffic | Volume | Cost Per Click |
|---|---|---|---|
| nano banana | 380 | 1.64M | $0.7 |
| 视频提示词反推 | 320 | 310 | -- |
| nano photo ai | 240 | 240 | -- |
| subtitle remover | 230 | 2.2K | $0.2 |
| nanophoto ai | 230 | 490 | -- |
Top Regions
| Region | Percentage |
|---|---|
| China | 49.75% |
| United States | 4.69% |
| Malaysia | 3.47% |
| Taiwan | 3.14% |
| India | 2.22% |
Seed Audio Alternatives
LOVO AI turns scripts into MP3 voiceovers in the browser, with 21 voice previews, permission-based voice cloning, 74-language speech, and a video editor.

Play HT is a free AI voice generator that turns text into speech with 200+ public voices, streams previews in the browser, and exports MP3 files.
MixVio runs 21 video, image and audio models in one browser workspace, plus 11 creator tools, with exact credit cost shown before every generation.
PodcastorAI turns PDFs, URLs, notes, and audio into studio-quality video podcasts with AI hosts, voices, and scripts for YouTube, Spotify, and TikTok.
KidVoice is an AI kid voice generator that creates natural child and teen voice audio from text with multilingual support and voice cloning.
Miso One AI is an AI voice generator that lets creators and development teams produce expressive dialogue audio, test cloning, review prompts, and download speech samples with credit tracking.
Petti Chat is an AI-powered web tool that lets pet owners capture short pet sounds, interpret likely intent in human language, and reply with calm, pet‑friendly audio, ensuring privacy and real‑time interaction.
GPT Realtime 2 is an AI voice generator for developers and product teams, offering realtime speech‑to‑speech interaction, low‑latency audio, prompt control, tool handoffs and downloadable session recordings.
GPT Realtime is an AI voice generator platform for developers and product teams, offering low‑latency speech‑to‑speech, image‑aware prompts, SIP call support, API workflow planning and reusable cache for rapid voice‑app prototyping.
This online PDF voice reader uses AI to convert documents, including scanned files via OCR, into natural speech in 142+ languages, supporting all PDF formats.
AnySpeech is a professional AI text to speech platform offering 100+ realistic voices across 50+ languages, designed for content creators, YouTubers, and podcasters worldwide.
FineVoice AI Voice Generator lets creators convert text to speech with realistic AI voices and clone voices in any style or language easily.